
Written by: Matt Beucler, CEO, Plura AI | Last updated: August 26, 2026
Key Takeaways
- Automated lead scoring machine learning replaces static rules-based systems with supervised models trained on CRM history, behavioral signals, and firmographic data to predict conversion probability.
- Standard batch ML pipelines retrain monthly or quarterly, which creates stale scores that miss live conversation signals and delay routing decisions.
- Production success requires 12 to 24 months of labeled CRM data, at least 200 closed-won deals, and time-based validation to prevent data leakage and reflect real-world performance.
- Key implementation steps include defining conversion targets, engineering time-windowed features, handling class imbalance, evaluating with precision@K, and monitoring for model drift.
- Plura AI removes batch retraining delays by updating lead scores in real time across every voice, SMS, RCS, or webchat interaction through its Stateful Conversation Database.
7-Step Implementation Checklist for Production Lead Scoring
- Define the conversion target. Frame the label as conversion to a paying customer within a fixed 30-, 60-, or 90-day window, not an open-ended “ever converted” flag. Align with sales on concrete criteria such as “has budget, a documented initiative, and a timeline within six months” before touching any data.
- Export and audit CRM history. Export 12 to 24 months of lead and opportunity history with clear conversion labels. Organizations with CRM data quality scores below 70% should fix data issues before training models, including “US” vs “United States” mismatches and inconsistent lifecycle-stage values.
- Engineer features from CRM and behavioral data. Derive recency, frequency, depth, velocity, and firmographic fit signals from raw records. Apply time-windowed construction using 7-, 14-, or 30-day rolling windows, because a short intent window avoids dilution from completed evaluations.
- Choose and train the model. Logistic regression is interpretable and fast to train. Gradient-boosted trees such as XGBoost or LightGBM handle mixed CRM and behavioral data types, capture non-linear relationships, and provide feature importance for explaining scores to sales teams. Require the minimum deal count discussed in the key takeaways before training. Below that threshold, most platforms recommend rules-based scoring instead.
- Handle class imbalance. Address class imbalance with SMOTE, class weights, or threshold tuning during model training, because conversion rates of 2 to 5 percent against non-converting traffic can cause an unweighted model to favor the majority class.2
- Select precision@K and write scores back to the CRM. Evaluate the model on precision in the top K scored leads rather than overall accuracy, because sales teams care about the quality of leads they receive, not performance across all leads. After validating precision at your chosen threshold, write the numeric score to a custom CRM property so routing workflows can act on it. Configure those workflows to trigger sales handoff above the threshold and nurture sequences below it so each lead receives the appropriate treatment.
- Set a retraining cadence with drift detection. Retrain when AUC falls below 0.85 or when win/loss analysis shows excessive false positives or negatives, feeding fresh conversion data weekly and reviewing metrics monthly.
Python Feature Pipelines for Automated Lead Scoring
Feature engineering drives model accuracy more than algorithm choice. High-impact features include email engagement velocity over 30 days, website visit recency and frequency, number of high-intent page views, firmographic fit score relative to the ideal customer profile, and content consumption depth.
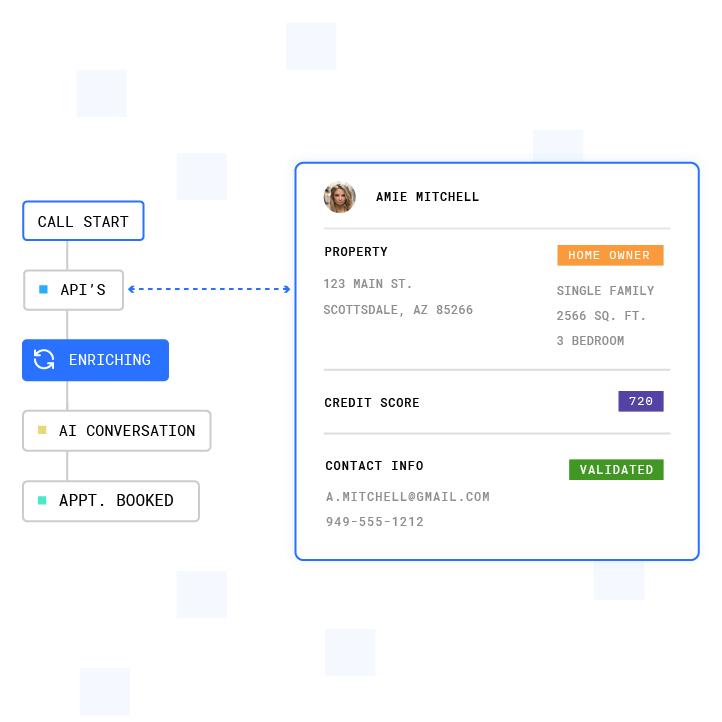
A production feature pipeline in Python pulls from the CRM API, computes rolling windows, and outputs a feature matrix. A minimal example for a 14-day engagement window:
import pandas as pd def build_features(events: pd.DataFrame, leads: pd.DataFrame, window_days: int = 14) -> pd.DataFrame: cutoff = pd.Timestamp.utcnow() - pd.Timedelta(days=window_days) recent = events[events["event_ts"] >= cutoff] agg = recent.groupby("lead_id").agg( page_views=("event_type", lambda x: (x == "page_view").sum()), pricing_views=("page_slug", lambda x: (x == "/pricing").sum()), email_opens=("event_type", lambda x: (x == "email_open").sum()), ).reset_index() return leads.merge(agg, on="lead_id", how="left").fillna(0) In 2026, firmographic pulls face tightening data-privacy constraints. Bulk third-party enrichment of personal attributes now intersects with state-level consumer privacy statutes in California, Virginia, and Colorado, among others.1 Waterfall enrichment across multiple data sources (typically 3 to 15) achieves 85 to 95 percent coverage on core firmographic fields, but each source must be evaluated against applicable data-use agreements before inclusion in a training pipeline. Teams should consult qualified counsel on the specific statutes that apply to their data flows.1
For tree-based models, passing NaN values directly for missing behavioral or firmographic signals allows the model to learn optimal splits. For logistic regression, apply KNN imputation by industry and revenue band or add binary missingness indicators to recover 1 to 3 AUC points.
End-to-End Automated Lead Scoring Example
This example shows an end-to-end flow using LightGBM with class weights and a HubSpot REST write-back:
import lightgbm as lgb from sklearn.model_selection import train_test_split import requests # 1. Train with class weights to handle imbalance X_train, X_test, y_train, y_test = train_test_split( X, y, test_size=0.2, stratify=y ) model = lgb.LGBMClassifier( class_weight="balanced", n_estimators=400, learning_rate=0.05, ) model.fit(X_train, y_train) # 2. Score new leads scores = model.predict_proba(X_new)[:, 1] # 3. Write scores back to HubSpot via REST HUBSPOT_TOKEN = "your_token" for lead_id, score in zip(lead_ids, scores): requests.patch( f="https://api.hubapi.com/crm/v3/objects/contacts/{lead_id}", headers={"Authorization": f="Bearer {HUBSPOT_TOKEN}"}, json={"properties": {"ml_lead_score": round(float(score), 4)}}, ) For Salesforce, replace the HubSpot PATCH with a Salesforce REST API PATCH to the Lead or Contact object’s custom field such as ML_Lead_Score__c. Authenticate with OAuth 2.0 connected app credentials. See Plura’s CRM integrations for native HubSpot and Salesforce connectors that remove the need for custom REST plumbing.
SMOTE is an alternative to class weights when the minority class is severely underrepresented:
from imblearn.over_sampling import SMOTE sm = SMOTE(random_state=42) X_resampled, y_resampled = sm.fit_resample(X_train, y_train) AI Lead Scoring Patterns in HubSpot
Once scores are written back to the CRM via REST API, the next step is configuring routing workflows that act on those scores. HubSpot’s workflow engine supports specific patterns that have become standard across B2B implementations. HubSpot implementations commonly create two separate custom score properties: a Fit Score and an Engagement Score, then route leads only when an agreed combination of the two crosses a defined threshold.
A production HubSpot routing workflow triggered by the combined threshold:
- Sets the contact lifecycle stage to Sales Qualified Lead.
- Assigns an owner via round-robin rotation or territory logic.
- Sends an internal notification to the assigned rep.
- Stamps a date property so SLA compliance can be measured.
Negative scoring attributes matter as much as positive ones. Careers-page visits, job applications, student signals, competitor domains, role emails, unsubscribes, and no-show meetings should be applied aggressively so that activity alone cannot outrank poor fit.
Plura’s native HubSpot integration writes real-time conversation scores from the Stateful Conversation Database directly to HubSpot contact properties on every touch, eliminating the manual REST calls above and removing the batch retraining dependency entirely.3 To see how that real-time update cadence affects revenue in your HubSpot environment, use Plura’s ROI calculator to model the impact against your current lead volume and conversion rates.
Lead Scoring Model Evaluation Metrics for RevOps
The table below compares three common algorithms for lead scoring across dimensions that matter to RevOps teams: training speed, interpretability for sales handoff, and ability to handle mixed CRM data types without manual encoding.
| Metric | Logistic Regression | LightGBM | XGBoost |
|---|---|---|---|
| Training speed | Fastest (seconds on 100K rows) | Fast (minutes on 100K rows) | Moderate (minutes on 100K rows) |
| Interpretability | High (coefficient weights) | Medium (SHAP values) | Medium (SHAP values) |
| Handles mixed data types natively | No (requires encoding) | Yes | Yes |
| Typical AUC on B2B CRM data | Depends on data quality and features | Depends on data quality and features with intent signals | Depends on data quality and features |
Precision@K is the primary production metric for RevOps teams because sales teams want to focus only on leads worth their effort. Evaluate the model on the percentage of leads in the top K scored band that actually convert. A supervised lead scoring model should be evaluated using precision@85, defined as the percentage of leads scoring above 85 that actually convert, in addition to AUC-ROC.
False-positive cost connects model performance to sales capacity. A false positive, which wastes SDR time on a poor lead, costs around $500 in opportunity cost, while a false negative can cost significantly more in lost revenue.2 Cost-weighted evaluation for lead scoring improves alignment with outcomes such as increased revenue and reduced wasted sales effort.
Time-Based Validation and Drift Monitoring
Time-based validation keeps evaluation honest for lead scoring models. Standard k-fold cross-validation shuffles records randomly, which leaks future data into training folds and inflates AUC estimates. Time-based validation instead splits the dataset chronologically, such as training on months 1 through 18 and validating on months 19 through 24. This mirrors production, where the model scores leads it has never seen.
A drift-detection loop monitors two signals between retraining runs:
- Score distribution shift: compare the distribution of scores on new leads against the distribution at training time using a Kolmogorov-Smirnov test. A p-value below 0.05 signals population drift.
- Label drift: track the rolling MQL-to-SQL conversion rate week over week. MQL-to-SQL conversion rates for well-calibrated B2B lead scoring models typically range from 20 to 40 percent.2 Sustained drops below internal targets indicate the model is no longer aligned with current buyer behavior.
Feed fresh conversion data weekly and review metrics monthly, triggering a full retrain when AUC falls below the threshold defined in your implementation checklist or when the sales acceptance rate drops materially.
Production Pitfalls and 2026 Privacy Constraints
The three most common production failures in automated lead scoring machine learning deployments are false-positive accumulation, firmographic data gaps, and feedback loop contamination.
False-positive accumulation occurs when the model’s score threshold is set too low to protect recall, which routes marginal leads to sales. Cost-weighted evaluation and threshold optimization align performance with revenue impact, risk tolerance, and sales capacity constraints rather than statistical correctness alone. Sales reps should record handoff outcomes via a dedicated property with accepted or rejected plus reason. These rejection reasons feed a weekly calibration report that compares routed leads by score band against downstream pipeline creation.
Firmographic data gaps are widening in 2026 as state consumer privacy statutes affect bulk third-party data pulls on individuals. Production feature engineering must address data freshness, entity resolution, missing-value handling, and feature versioning at the same time. Teams should consult qualified counsel on applicable statutes before building enrichment pipelines that pull personal attributes from third-party sources.1
Feedback loop contamination occurs when only sales-contacted leads generate closed-won labels, which biases the model toward leads that look like past outreach targets rather than leads most likely to convert. Correct this by including a random exploration sample of 5 to 10 percent of leads routed outside the model’s top-K band each quarter, then labeling their outcomes for the next training run.
ROI Measurement: Revenue-per-Contacted-Lead vs Rules-Based Baseline
Revenue-per-contacted-lead (RPCL) is a practical metric for comparing an ML scoring model against a rules-based baseline because it captures both conversion rate and deal size without requiring a controlled experiment. Calculate it as total closed revenue divided by total leads contacted in a given period, segmented by scoring method.
A practical comparison framework:
- Run the rules-based model and the ML model in parallel for 60 days, routing alternating cohorts.
- Record RPCL, MQL-to-SQL conversion rate, and sales capacity consumed in hours per contacted lead for each cohort.
- Compute the lift as ML RPCL minus rules RPCL, divided by rules RPCL.
- Annualize the lift against total lead volume to produce a revenue impact figure for leadership.
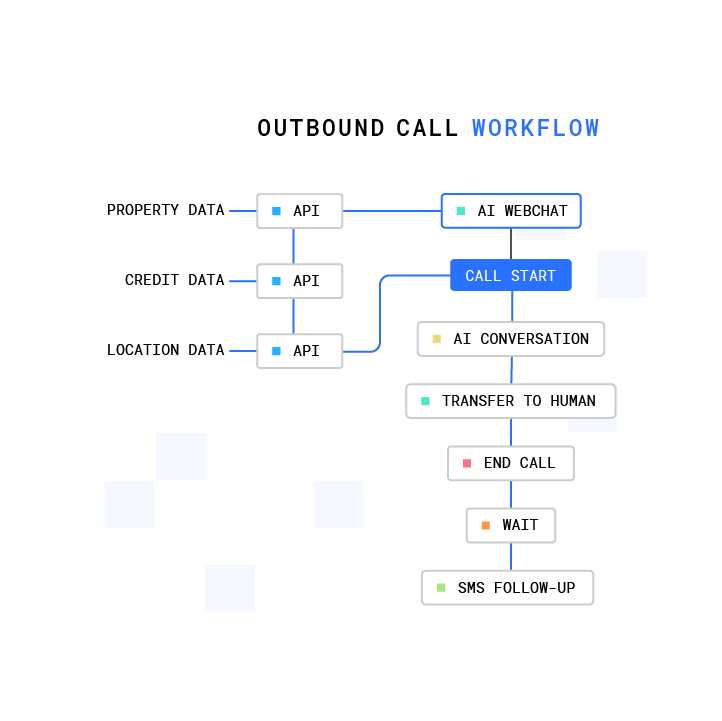
Batch ML pipelines introduce a structural gap in this measurement. Scores are stale between retraining runs, so a lead whose intent accelerated after the last batch job carries an outdated score when the rep calls. Plura removes this gap. Plura’s Business Intelligence layer scores and prioritizes leads in real time using behavioral signals, conversation context, and predictive intent modeling. The Stateful Conversation Database updates the score on every voice, AI SMS, RCS, or AI webchat touch, not on a 30-to-90-day batch cycle. That means the score the rep sees when they open a contact record reflects what happened on this morning’s call, not last month’s training snapshot. The calculator above walks through RPCL lift scenarios for your lead volume, so you can run your numbers and quantify the batch-versus-real-time gap.
Conclusion: Moving From Static Scores to Live Intent
A production automated lead scoring machine learning model is achievable inside a 90-day window for RevOps teams that meet the data requirements outlined above. The 7-step checklist covers conversion target definition, feature engineering, model selection, class-imbalance handling, precision@K evaluation, CRM write-back, and drift-monitored retraining. The structural ceiling on batch ML is the retraining cycle itself. Scores go stale between runs, and live conversation signals do not reach the model in time to affect routing decisions.
Plura’s Stateful Conversation Database removes that ceiling by treating every interaction as a scoring event. The AI Lead Intelligence layer enriches and scores leads in real time during the conversation, across every channel, so the score in your CRM reflects the lead’s current intent state rather than their state at the last batch run. For RevOps teams that need to ship a working model and demonstrate RPCL lift to sales leadership within 90 days, this difference separates a model that improves over time from one that is always catching up. Before presenting the business case to sales leadership, you can model your 90-day RPCL improvement using Plura’s calculator.
Frequently Asked Questions
What is the minimum data requirement to build an automated lead scoring machine learning model?
A reliable supervised lead scoring model requires at least 200 closed-won deals as positive examples and a comparable volume of closed-lost records as negative examples. Below 100 to 200 positive examples, most commercial tools recommend rules-based scoring instead. Most practitioners recommend exporting 12 to 24 months of CRM history so the training set covers enough seasonal and market variation to generalize to new leads. Before training, CRM data should meet three readiness criteria: at least 1,000 to 2,000 labeled records in total, standardized categorical fields with no free-text variants for industry or lead source, and reliable outcome tracking for every record. Organizations with data quality scores below 70 percent should resolve data issues before beginning model development.
How does Plura AI’s approach differ from a standard batch ML lead scoring pipeline?
Standard batch ML pipelines for lead scoring models retrain on a fixed cadence of monthly or quarterly, typically 30 to 90 days, which means scores are stale between runs. A lead whose intent accelerated after the last training job carries an outdated score when a rep contacts them. Plura’s Stateful Conversation Database updates lead scores on every interaction across voice, SMS, RCS, and webchat in real time. The AI Lead Intelligence layer enriches and scores leads during the live conversation using behavioral signals and conversation context, not a snapshot from last month’s training run. This approach reduces structural lag from batch pipelines and helps ensure the score in the CRM reflects the lead’s current intent state at the moment of contact.
What evaluation metrics should RevOps teams use to assess a lead scoring model in production?
Overall accuracy is an unreliable metric for lead scoring because conversion rates of 2 to 5 percent mean a model that predicts “no conversion” for every lead can achieve high accuracy while being operationally useless. The primary metrics for production evaluation are precision@K, which measures the percentage of leads in the top K scored band that actually convert, AUC-ROC, which measures the model’s ability to rank converting leads above non-converting ones, and sales acceptance rate, which measures the percentage of routed leads that sales reps agree are high quality. Revenue-per-contacted-lead is the business-level metric that connects model performance to pipeline impact. False-positive cost, estimated at approximately $500 in SDR opportunity cost per wasted contact, should be factored into threshold selection alongside false-negative cost.
How should lead scores be written back into HubSpot or Salesforce, and what routing rules are standard?
In HubSpot, the standard pattern creates two custom score properties: a Fit Score derived from firmographics and role, and an Engagement Score derived from recent behavioral signals. A routing workflow triggers when the combined score crosses a defined threshold, setting the lifecycle stage to Sales Qualified Lead, assigning an owner via round-robin or territory logic, notifying the rep, and stamping a date property for SLA tracking. A second workflow routes high-fit but low-engagement leads into nurture sequences rather than immediate sales handoff. In Salesforce, the equivalent pattern writes the ML score to a custom field on the Lead or Contact object via the REST API and triggers a Process Builder or Flow that executes the same routing logic. Plura’s native HubSpot and Salesforce integrations write real-time conversation scores from the Stateful Conversation Database directly to these CRM properties on every touch, which removes the need for custom REST plumbing.
How do 2026 data-privacy constraints affect firmographic feature engineering for lead scoring models?
State-level consumer privacy statutes in California, Virginia, Colorado, and other jurisdictions increasingly describe how third-party personal data can be collected, processed, and used in automated decision-making systems. For B2B lead scoring, the practical impact falls on firmographic enrichment pipelines that pull individual-level attributes from third-party data brokers. Teams building or updating lead scoring models in 2026 should audit each enrichment source against applicable data-use agreements and consult qualified counsel on the specific statutes that govern their data flows before including third-party personal attributes in a training pipeline.1 First-party behavioral signals collected directly from owned channels, such as website visits, email engagement, and CRM activity, carry different privacy considerations and are typically among the strongest individual predictors in lead scoring models for accounts already in the funnel.
1 This article describes regulatory frameworks at a general level and does not constitute legal advice. Laws and regulations vary by jurisdiction, change over time, and apply differently depending on facts and circumstances. Readers should consult qualified legal counsel before making compliance decisions.
2 Performance figures, customer outcomes, and industry statistics referenced in this article are drawn from cited third-party sources or Plura customer case studies. Individual results vary based on implementation, use case, industry, audience, and execution. Past or aggregate performance is not a guarantee of future results.
3 References to third-party products, services, companies, or research are made for informational and comparative purposes only. Plura AI is not affiliated with, endorsed by, or sponsored by any third party named in this article unless explicitly stated. Trademarks and product names referenced remain the property of their respective owners.
This article is provided for informational purposes only and reflects Plura AI’s understanding at the time of publication. Product capabilities, integrations, and specifications are subject to change. For the most current information, visit plura.ai.
This article was produced with the assistance of AI tools and reviewed by Plura AI prior to publication.